
Cleaning Time Series Data in Python: A Practical Guide
Cleaning real-world time series data is complex due to its inherent temporal ordering. This guide provides a Python pipeline covering essential steps like auditing, reindexing, strategic missing value imputation, context-aware outlier detection, duplicate handling, frequency alignment, noise smoothing, and automated validation. It emphasizes domain-specific decisions and practical techniques for building robust data processing workflows.

Time series data, ubiquitous in modern systems from IoT sensors to financial markets, is rarely pristine. Sensors fail, networks glitch, and human error is inevitable. Unlike static tabular data, cleaning time series introduces unique challenges: the temporal order is a structural constraint that cannot be violated without corrupting the data's integrity. Simply shuffling rows or imputing a missing value with a global mean can destroy future-past relationships crucial for analysis and modeling.
This guide outlines a comprehensive Python-based pipeline for cleaning time series data, ensuring it's robust and ready for feature engineering or machine learning. We'll leverage pandas, numpy, scipy, scikit-learn, and statsmodels to tackle common issues such as missing values, outliers, duplicates, and noise.
bash pip install pandas numpy scipy scikit-learn statsmodels
Auditing and Reindexing Your Time Series
The first principle of data cleaning is to understand the scope of the problem. Before any modifications, conduct a thorough audit:
- Time Index: Is it regular? Are there gaps? Is it monotonic?
- Missing Values: How many? Are they isolated or clustered?
- Value Range: Are there values that are physically impossible or indicate sensor failure?
- Duplicate Timestamps: Do multiple entries exist for the same timestamp?
A critical pre-cleaning step is ensuring your time index is regular. Often, missing timestamps are simply absent, not represented as NaN rows. pd.infer_freq returning None signals this irregularity. Reindexing to a canonical frequency (e.g., hourly, daily) explicitly introduces NaNs for missing observations, allowing imputation methods to find them.
python import pandas as pd import numpy as np
Simulate a sensor feed with missing timestamps (not just missing values)
periods = 168 index = pd.date_range("2024-06-01", periods=periods, freq="H") voltage = ( 230.0 + 3.5 * np.sin(2 * np.pi * np.arange(periods) / 24) + np.random.normal(0, 1.2, periods) ) series = pd.Series(voltage, index=index, name="voltage_v") irregular_index = index.delete([14, 15, 16, 42, 101, 102, 103]) irregular_series = series.dropna().reindex(irregular_index)
print(f"Inferred freq before reindex: {pd.infer_freq(irregular_series.index)}") # Expected: None
Reindex to the full canonical hourly grid
canonical_index = pd.date_range( start=irregular_series.index.min(), end=irregular_series.index.max(), freq="H" ) reindexed = irregular_series.reindex(canonical_index)
print(f"Inferred freq after reindex: {pd.infer_freq(reindexed.index)}") # Expected: H print(f"Missing values after reindex: {reindexed.isna().sum()}")
Handling Missing Values Strategically
The approach to missing values depends on the signal's nature and gap length.
Forward Fill (ffill)
Best for step-function signals (e.g., machine states, categorical flags) where the last known value persists until a change occurs.
Time-Weighted Interpolation
For continuous signals, interpolate(method="time") is robust. It linearly estimates missing values, respecting the actual time difference between points, which is crucial for irregularly spaced data.
python
Fill the voltage series using time-based interpolation
voltage_clean = reindexed.interpolate(method="time")
gap_window = voltage_clean["2024-06-01 12:00":"2024-06-01 18:00"] original_window = reindexed["2024-06-01 12:00":"2024-06-01 18:00"] comparison = pd.DataFrame({ "original": original_window, "interpolated": gap_window.round(3), "was_missing": original_window.isna(), }) print("Time-Weighted Interpolation Example:") print(comparison)
Seasonal Decomposition Imputation
For long gaps in seasonal signals, simple interpolation falls short. statsmodels.tsa.seasonal.seasonal_decompose can break a series into trend, seasonal, and residual components. You can then interpolate or impute each component separately before reconstructing the series. This preserves underlying patterns.
Detecting and Treating Outliers
Outliers in time series demand temporal context. A value might be an outlier globally but perfectly normal locally, or vice-versa. Context-aware methods are essential.
Z-Score with Rolling Window
A global Z-score is insufficient for non-stationary data. A rolling Z-score identifies values that are statistically unusual relative to their local neighborhood, making it suitable for capturing transient spikes or dips.
python window = 24 # 24-hour rolling window roll_mean = voltage_clean.rolling(window, center=True, min_periods=1).mean() roll_std = voltage_clean.rolling(window, center=True, min_periods=1).std() rolling_z = (voltage_clean - roll_mean) / roll_std threshold = 3.0 outliers_z = rolling_z[rolling_z.abs() > threshold] print(f" Rolling Z-score outliers detected: {len(outliers_z)}") print(outliers_z.round(3))
IQR-Based Outlier Detection
The Interquartile Range (IQR) method is more robust than Z-score for non-Gaussian distributions. It defines outliers as points falling outside [Q1 - 1.5*IQR, Q3 + 1.5*IQR].
Outlier Treatment
Once identified, outliers can be:
- Winsorized: Capping extreme values at a plausible threshold. This retains the anomaly's presence but limits its impact.
- Replaced: Treating outliers as missing data and interpolating (e.g., with
interpolate(method="time")). This is appropriate if the value is deemed a measurement error.
Removing Duplicates and Aligning Frequencies
Duplicate timestamps, often a result of pipeline retries, can skew aggregations. If timestamps are identical, decide whether to keep='first' (assuming the first recorded value is correct) or average them (groupby(level=0).mean()).
Real-world data often arrives at disparate frequencies (e.g., 1-minute sensor data, hourly weather). resample() is crucial for frequency alignment. The aggregation method (e.g., mean, max, sum) during resampling must be chosen based on the domain context. For power data, mean provides average load, max gives peak demand, and sum (with appropriate scaling) yields total energy (kWh).
python
1-minute power draw readings
power_1min = pd.Series( 42 + 18 * ((pd.date_range("2024-06-01", periods=1440, freq="T").hour.isin(range(8, 19)))).astype(int) + np.random.normal(0, 2, 1440), index=pd.date_range("2024-06-01", periods=1440, freq="T"), name="power_kw" )
Downsample to hourly: mean, max, sum (energy)
power_hourly_mean = power_1min.resample("H").mean().round(2) power_hourly_max = power_1min.resample("H").max().round(2) energy_hourly_kwh = (power_1min.resample("H").sum() / 60).round(3)
print(" Frequency Alignment and Resampling Example (Hourly Power):") print(pd.DataFrame({"mean_kw": power_hourly_mean, "peak_kw": power_hourly_max, "energy_kwh": energy_hourly_kwh}).iloc[7:13])
Smoothing Noise
Raw sensor data often contains high-frequency noise. Smoothing can reveal the underlying signal, but over-smoothing risks destroying genuine variability.
Exponential Weighted Moving Average (EWMA)
EWMA assigns more weight to recent observations, making it adaptive to changes in the signal's level, outperforming simple moving averages for non-stationary data.
python
Noisy temperature sensor (°C)
temp_noisy = pd.Series( 3.5 + 1.2 * np.sin(2 * np.pi * np.arange(168) / 24) + np.random.normal(0, 0.8, 168), index=pd.date_range("2024-06-01", periods=168, freq="H"), name="temperature_c" ) temp_ewma = temp_noisy.ewm(span=6, adjust=False).mean()
print(" EWMA Smoothing Example:") print(pd.DataFrame({"raw": temp_noisy, "ewma": temp_ewma.round(3)}).iloc[22:30])
Savitzky-Golay Filter
When preserving peak shapes is important, the Savitzky-Golay filter fits a polynomial across a sliding window, smoothing noise while retaining the height and width of genuine spikes better than simple moving averages.
Schema and Sanity Validation
Cleaning is incomplete without automated validation. Implement checks that run after cleaning (and ideally, before). This catches regressions or new data issues before they affect downstream models. Validation should verify frequency, missing value rates, value ranges, duplicate absence, and index monotonicity.
python def validate_time_series(series: pd.Series, config: dict) -> dict: report = {} report["freq_regular"] = pd.infer_freq(series.index) == config["expected_freq"] report["missing_below_threshold"] = series.isna().mean() <= config["max_missing_rate"] report["values_in_range"] = series.dropna().between(config["min_value"], config["max_value"]).all() report["no_duplicates"] = not series.index.duplicated().any() report["index_monotonic"] = series.index.is_monotonic_increasing return report
config = { "expected_freq": "H", "max_missing_rate": 0.05, "min_value": 210.0, "max_value": 250.0, } report = validate_time_series(voltage_clean, config) print(" === VALIDATION REPORT ===") for check, result in report.items(): status = "✓ PASS" if result else "✗ FAIL" print(f" {status} {check}")
Implementing a robust cleaning pipeline, from initial audit to final validation, is non-negotiable for reliable time series analysis and modeling. Each step requires careful consideration of the signal's characteristics and the domain's specific needs.
FAQ
Q: Why is cleaning time series data more challenging than cleaning tabular data? A: Time series data has a critical structural constraint: temporal ordering. Cleaning decisions must respect this order, preventing future information from influencing past observations. This makes tasks like imputing missing values or detecting outliers more complex, as context must often be localized to a specific time window rather than global statistics.
Q: When should I use time-weighted interpolation versus seasonal decomposition for missing values?
A: Time-weighted interpolation (method="time") is ideal for continuous signals with relatively short, irregular gaps, as it linearly estimates values based on time proximity. Seasonal decomposition imputation is more suitable for longer gaps in signals exhibiting clear seasonal patterns, as it reconstructs missing data by leveraging the observed trend and seasonality, which simple interpolation would ignore.
Q: What's the trade-off between Winsorization and interpolation for outlier treatment? A: Winsorization caps extreme outlier values at a specified threshold, retaining the fact that an anomaly occurred but mitigating its disproportionate impact. This is useful when you want to acknowledge the event's presence. Interpolation, by treating the outlier as missing and replacing it, assumes the value was erroneous and aims to restore the underlying signal, which is preferable if the outlier is purely noise or a sensor error.
Related articles

DJI Solo Video Setups: Smart Choices for Lone Creators
This review delves into DJI's recommended solo video setups, highlighting the Osmo Pocket 3 Creator Combo as a top pick for its integrated camera, gimbal, and mic. It also covers stabilizers like the Osmo Mobile 8 and RS 4, and the DJI Mic Mini series for enhanced audio, providing honest pros, cons, and clear buying advice.
TCG Pocket Responds: A Much-Needed Pace Shift for Pokémon Fans
Pokémon TCG Pocket is rolling out a major update for its second anniversary, primarily addressing player concerns about overwhelming content releases by shifting to a six-week set schedule. This aims to curb player decline and improve overall engagement by giving trainers more time to collect and strategize. The update also adds new collection methods, improved deck-building features, and enhanced trading functionality.
Ditch Merge & Center: The Better Way to Align Text in Excel
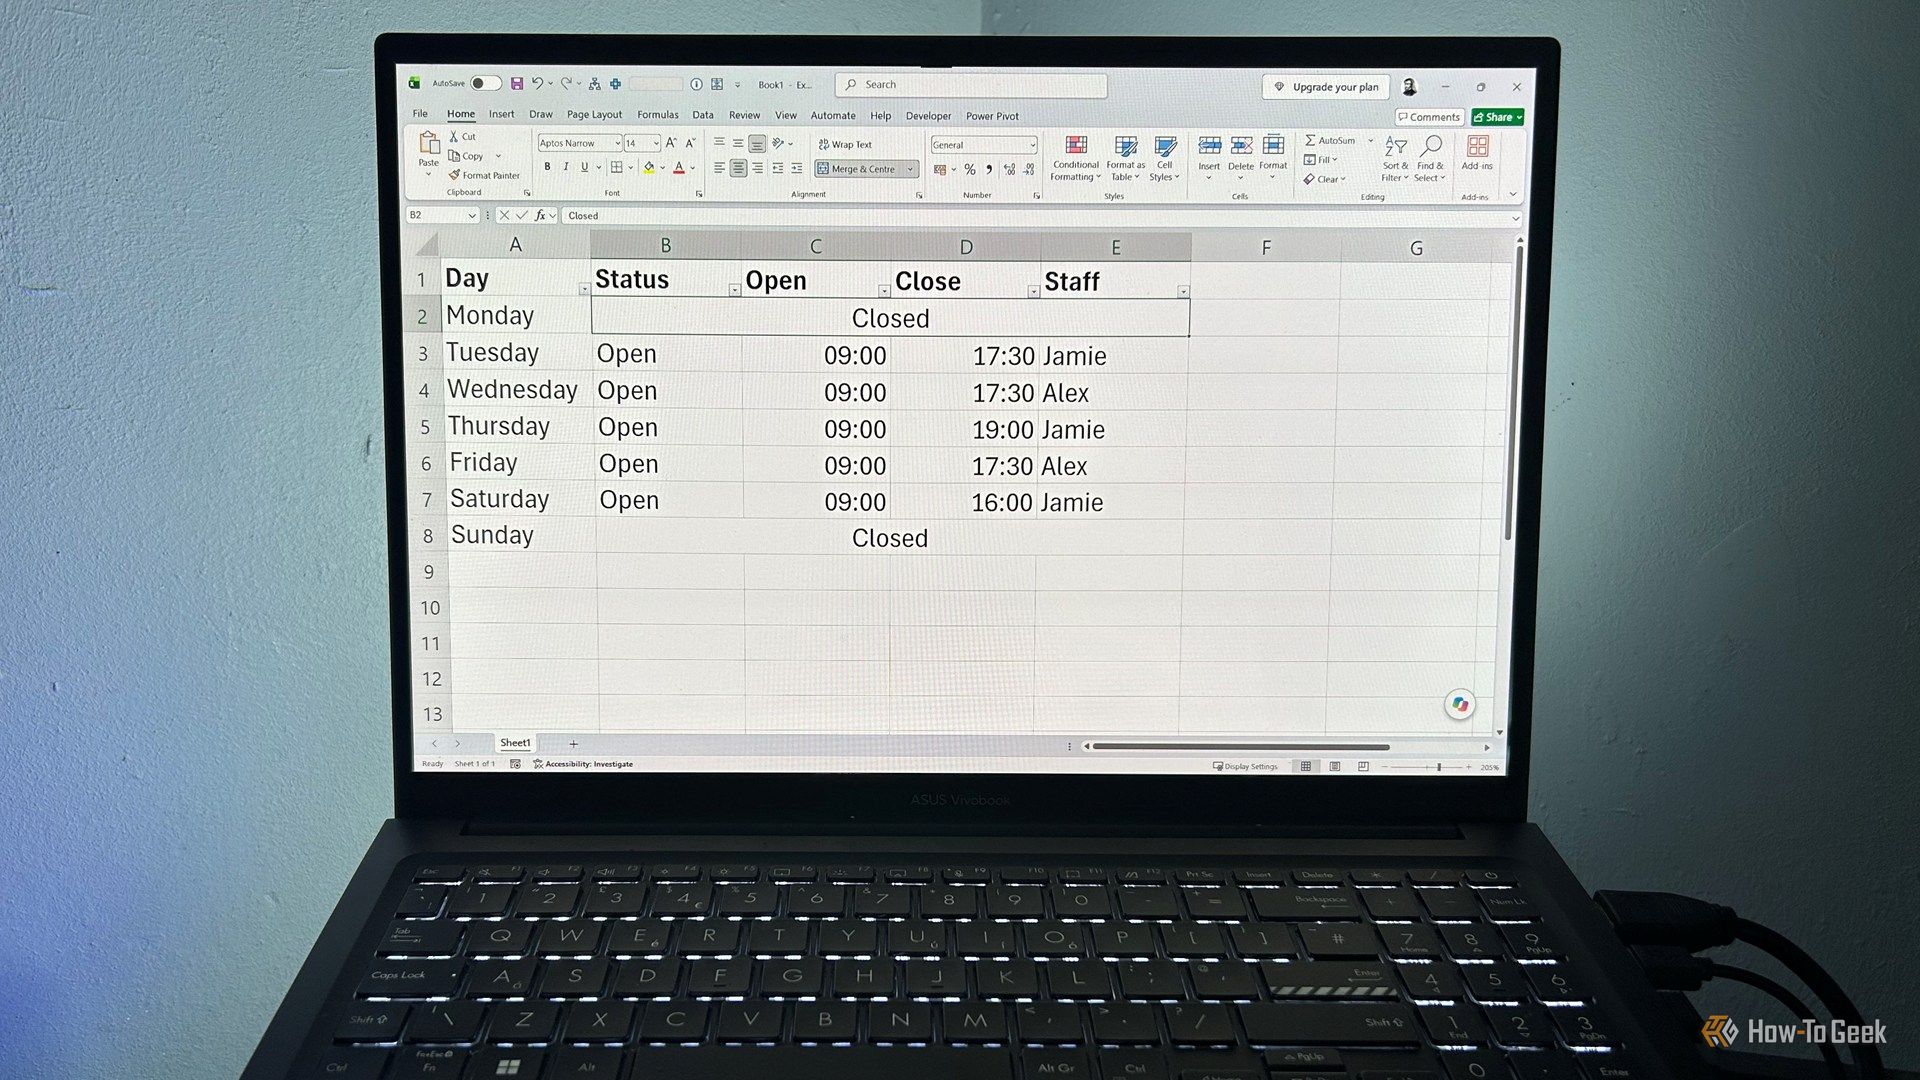
Learn to use Excel's "Center Across Selection" to align text across cells without merging, avoiding common data manipulation issues. This guide provides steps to utilize this newly accessible feature and add it to your Quick Access Toolbar.

AI's Confidence vs. Formal Methods' Rigor: Design Flaws & Verification
While AI accelerates code generation, formal methods remain critical for ensuring system correctness. Languages like TLA+ and tools like Quint enable developers to model and verify system designs before coding, catching subtle flaws. Quint makes formal methods more accessible with developer-friendly syntax and executability. This approach is vital for verifying AI-generated code through trace validation and model-based testing, ensuring reliability against real-world data.
regional: A two-person Seattle startup lands $1M to reinvent
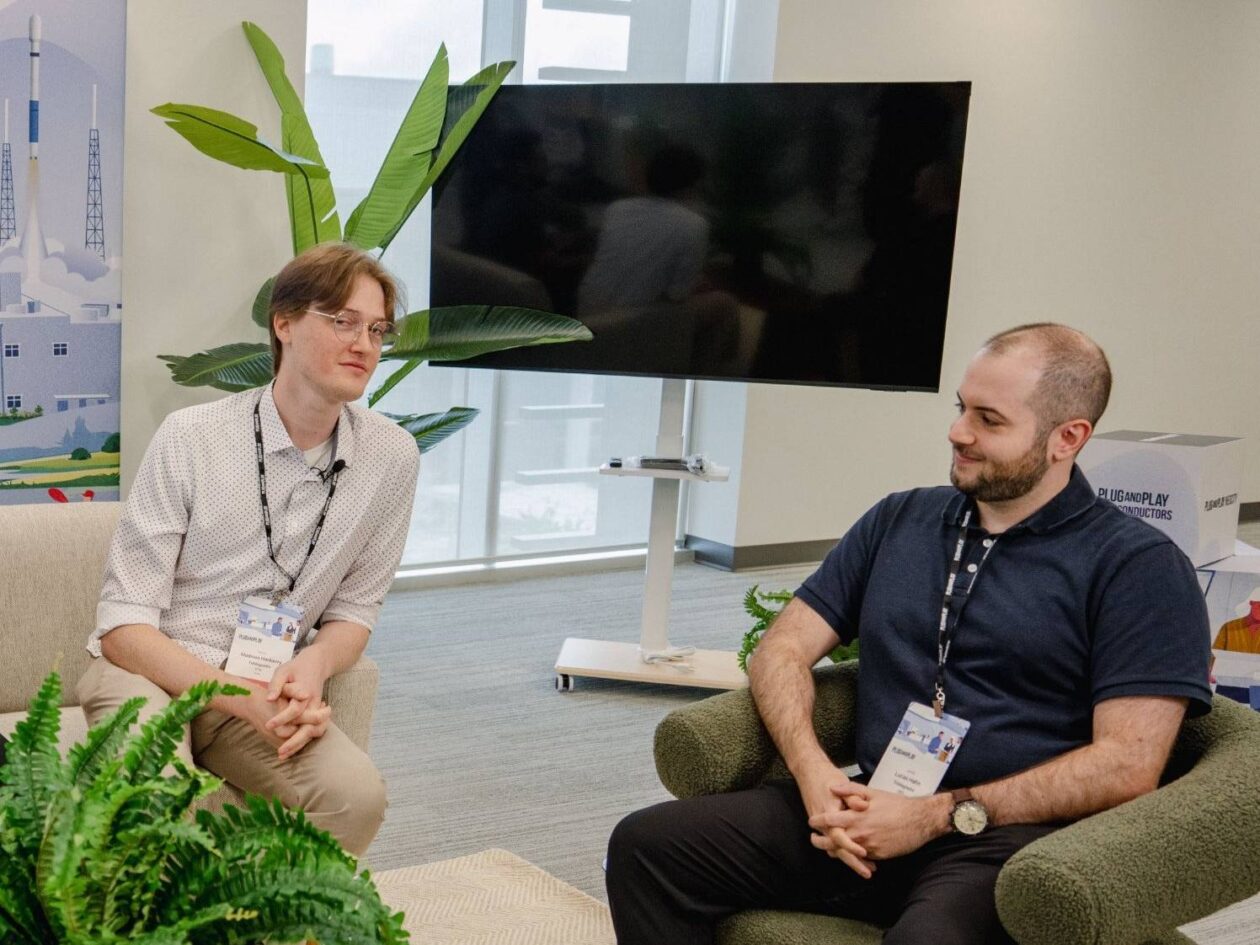
Seattle startup TriMagnetix has secured $1 million to develop semiconductor chips that consume 800 times less energy and are radiation-resistant. The two-person company, leveraging nanomagnetic technology, is targeting space applications and data centers. With new funding and key partnerships, TriMagnetix aims for commercial sales within a year.

Ephemeral PR Preview Environments on GKE: A Deep Dive
Every development team eventually grapples with the limitations of shared staging environments. The familiar scenario: multiple features deployed simultaneously, database migrations clashing, and the phrase "it works on