
Mastering Conversational AI QA: A Developer's Practical Guide
Traditional software testing patterns often falter with conversational AI due to its dynamic nature. This guide provides practical strategies for QA engineers and developers to effectively test AI agents, focusing on intent, conversational flow, robustness against hallucinations, and strategic, risk-based approaches to ensure reliable and user-friendly interactions.

As software developers, our testing muscle memory is trained on deterministic patterns: input, exact expected output, and a clear pass/fail. This paradigm, however, buckles when applied to conversational AI. An AI agent might answer "How do I reset my password?" with several distinct yet equally valid phrases. The challenge isn't just verifying correctness, but understanding how to test a system whose "correct" response can vary dynamically. This guide explores practical strategies for QA engineers to navigate conversational AI testing, adapting traditional techniques to this uniquely fluid domain.
Testing Intent and Evaluating Response Quality
The fundamental shift in conversational AI QA is focusing on intent rather than exact wording. Multiple user utterances like "I forgot my password," "Can't access my account," or "Password isn't working" may all map to a single PASSWORD_RESET intent. Testing involves ensuring the AI consistently and accurately identifies the underlying user goal across a broad range of phrasing, including misspellings, abbreviations, and informal language.
python test_cases = [ { "message": "I forgot my password", "expected_intent": "PASSWORD_RESET" }, { "message": "How do I change my password?", "expected_intent": "PASSWORD_RESET" }, { "message": "Can't get into my account", "expected_intent": "PASSWORD_RESET" }, ] for test in test_cases: response = ai_agent.send(test["message"]) assert response.intent == test["expected_intent"]
Similarly, avoid rigid string comparisons for AI responses. Instead, define properties a good response must contain. For a password reset, criteria might include: explaining how to start the process, providing an actionable next step, and avoiding requests for sensitive information. This property-based evaluation allows for semantic correctness without demanding lexical identity. Beyond correctness, assess responses across dimensions like:
- Accuracy: Factual truth of the information.
- Relevance: How well the AI addresses the user's question.
- Completeness: Providing all necessary information.
- Clarity: Ease of understanding.
- Helpfulness: Actual utility in achieving the user's goal. A simple scoring rubric can formalize these evaluations, moving beyond subjective judgments.
Testing Conversational Flow and Adaptability
Conversational AI operates within a dialogue, not isolated queries. Therefore, multi-turn testing is critical to verify context retention. Does the AI remember previous information when a user asks a follow-up like "Can I do that online?" or "When will it arrive?" after providing an order number?
python ai_agent.send("My order number is A10245") response = ai_agent.send("When will it arrive?") assert response.order_id == "A10245"
Also, users make mistakes or change their minds. Test corrections: if a user states "My account number ends in 4567," then quickly corrects to "Sorry, I meant 4576," the AI should update its context. Finally, address ambiguity. When faced with vague inputs like "I want to change it," a well-designed AI shouldn't guess. Instead, it should exhibit clarification behavior, asking questions like "What would you like to change?" These tests confirm the AI's ability to identify informational gaps and prompt for necessary details.
Ensuring Robustness: Knowledge, Hallucinations, and Fallbacks
The quality of an AI's response is often tied to its knowledge base. If the AI retrieves outdated or conflicting information (common in RAG systems), it will produce an incorrect answer, even if the model performs perfectly. QA must investigate the source of information for accuracy, currency, and consistency.
Crucially, test for hallucinations. Ask about non-existent products or policies (e.g., "What's the cancellation policy for Product Z?"). The AI should gracefully admit ignorance ("I don't have information about Product Z") or offer to escalate, rather than inventing details.
Even the most advanced AI will eventually misunderstand. Fallback behavior is key here. Rather than an endless loop of "Sorry, I don't understand," a robust system should offer clarification or alternative paths. Test various failure scenarios, from unknown intents to repeated misunderstandings. When the AI reaches its limits, it should initiate human escalation. Test the entire handoff process: Does the AI correctly identify the need for human intervention? Is conversation context preserved for the human agent, preventing the user from repeating themselves?
Strategic QA for Conversational AI
Conversational AI often acts as a natural language interface to complex backend systems. Thus, traditional integration testing remains vital. Verify correct API mapping, handle authentication failures, timeouts, and ensure service availability. The AI layer adds complexity; it doesn't eliminate foundational testing.
To ensure repeatability, build a golden dataset: a curated collection of representative user inputs and expected AI behaviors. This dataset can serve as a robust regression suite whenever the AI's models, knowledge, or logic are updated.
Measuring success also evolves. Beyond a simple pass rate, track impact-oriented metrics like intent recognition accuracy, task completion rate, fallback rate, grounding failures (conflicts with approved knowledge), and critical hallucinations. This informs risk-based conversational testing, prioritizing scenarios where AI failure poses the highest harm, ensuring critical flows receive the most thorough validation.
FAQ
Q: How does testing for "intent" differ from traditional functional testing of a text field?
A: Traditional text field testing often involves validating specific inputs against exact expected outputs (e.g., "submit" button click after filling form). Intent testing, however, focuses on the meaning or goal behind a user's varied textual inputs, regardless of their specific phrasing. For example, "reset my password," "forgot login," and "can't get into account" all map to the same PASSWORD_RESET intent, which is the functional outcome being tested, rather than the lexical exactness of the input.
Q: What are "hallucinations" in the context of conversational AI testing? A: Hallucinations occur when a conversational AI confidently generates information that is factually incorrect, unsupported by its knowledge base, or entirely fabricated. In testing, this is critical because a hallucination can mislead users significantly. Testers aim to provoke hallucinations (e.g., asking about non-existent products) to ensure the AI responds by admitting ignorance, asking for clarification, or escalating to a human, rather than inventing an answer.
Q: Why is a "golden dataset" more valuable than ad-hoc exploratory testing for conversational AI? A: While exploratory testing is crucial for initial discovery and understanding AI behavior, a golden dataset provides a standardized, repeatable, and scalable method for regression testing. It's a curated set of known good inputs and expected behaviors that can be automatically re-run whenever the AI system changes. This ensures that new deployments don't introduce regressions in previously validated areas, something ad-hoc testing struggles to guarantee over time.
Related articles
Android 17 QPR2 Beta 7.1: The Performance Relief You've Been Waiting
Android 17 QPR2 Beta 7.1: Finally Fixing the QPR1 Performance Woes Verdict: Android 17 QPR2 Beta 7.1 is a crucial and highly anticipated software update for Google Pixel users, specifically targeting and resolving the
TCG Pocket Responds: A Much-Needed Pace Shift for Pokémon Fans
Pokémon TCG Pocket is rolling out a major update for its second anniversary, primarily addressing player concerns about overwhelming content releases by shifting to a six-week set schedule. This aims to curb player decline and improve overall engagement by giving trainers more time to collect and strategize. The update also adds new collection methods, improved deck-building features, and enhanced trading functionality.
Ditch Merge & Center: The Better Way to Align Text in Excel
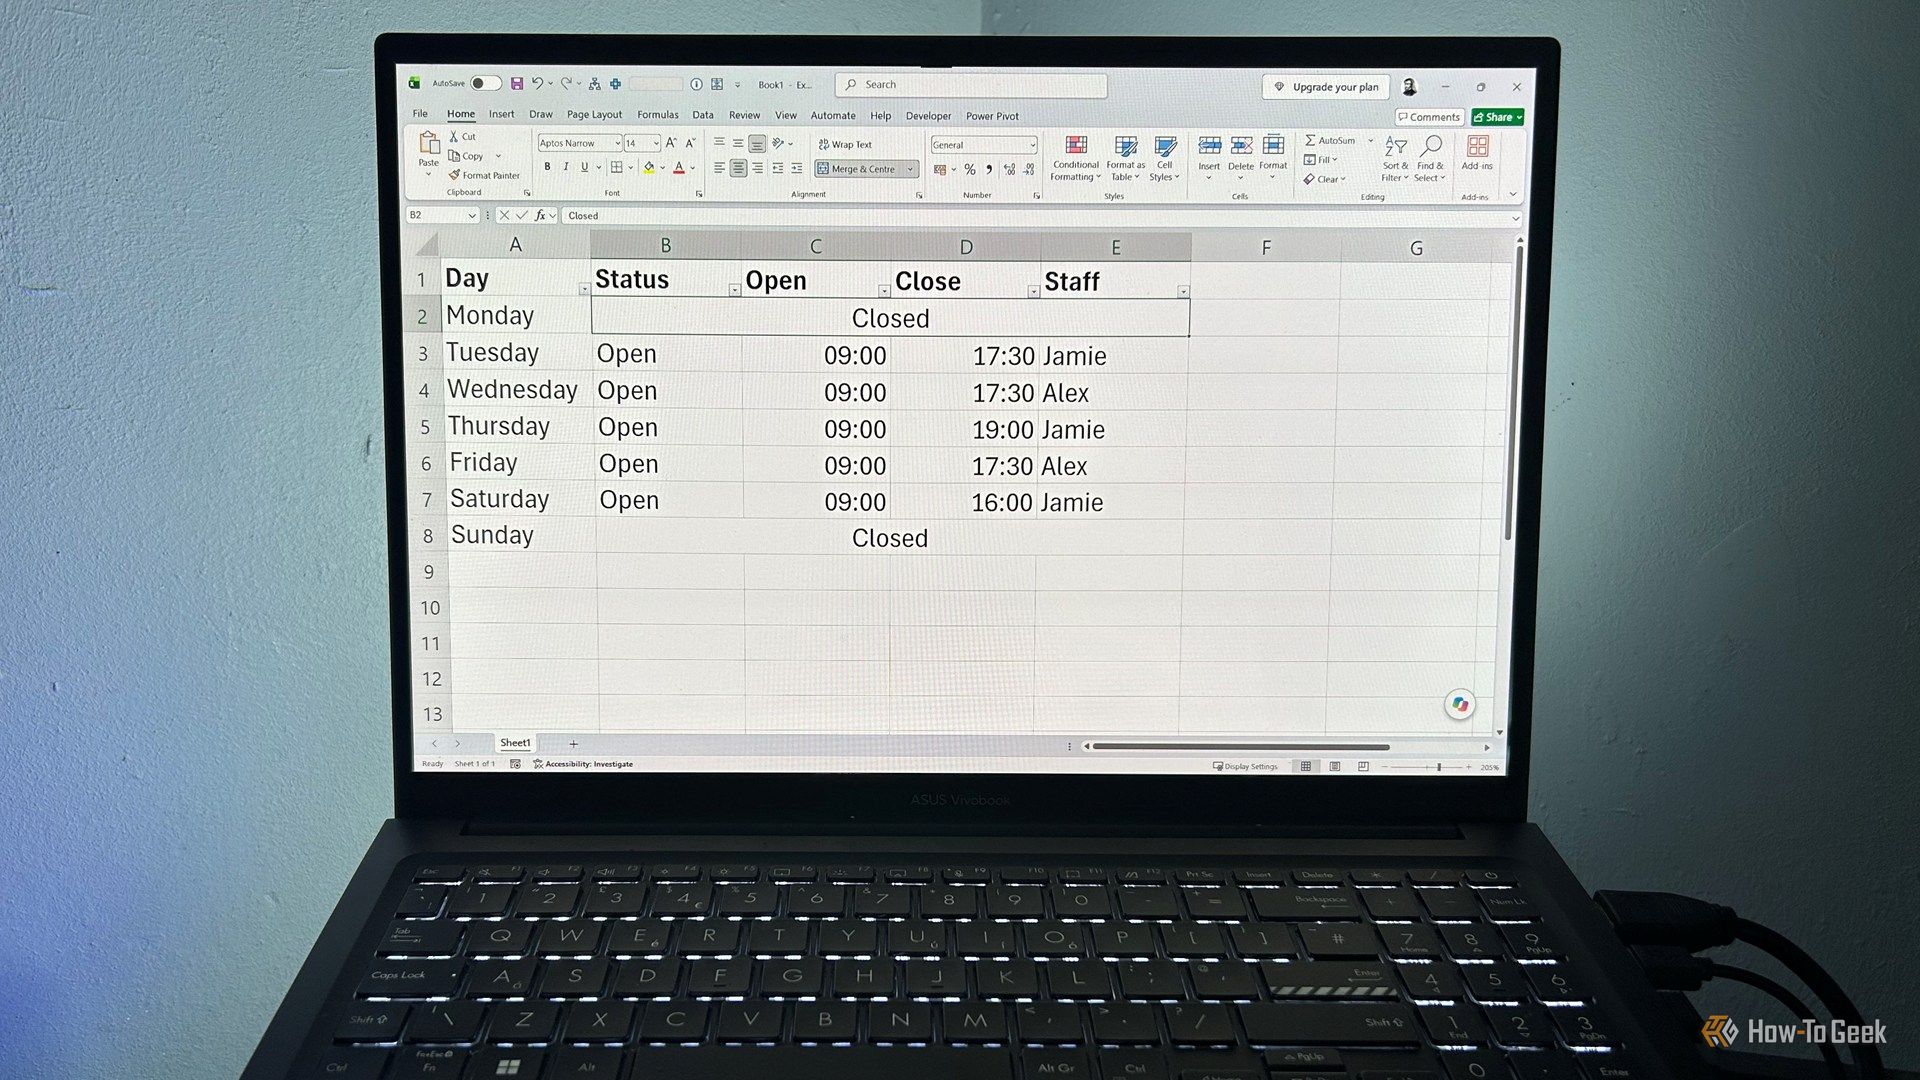
Learn to use Excel's "Center Across Selection" to align text across cells without merging, avoiding common data manipulation issues. This guide provides steps to utilize this newly accessible feature and add it to your Quick Access Toolbar.

Mark Wahlberg on using AI in film ‘the right way’ and being open to
Actor Mark Wahlberg believes AI has a place in filmmaking if used responsibly for enhancement, not script generation or actor replacement. At TechCrunch Disrupt, he expressed openness to an AI likeness carrying on his legacy, managed by his family, and emphasized storytelling.
Apple iPhone Duo: A Daring Debut with Notable Compromises
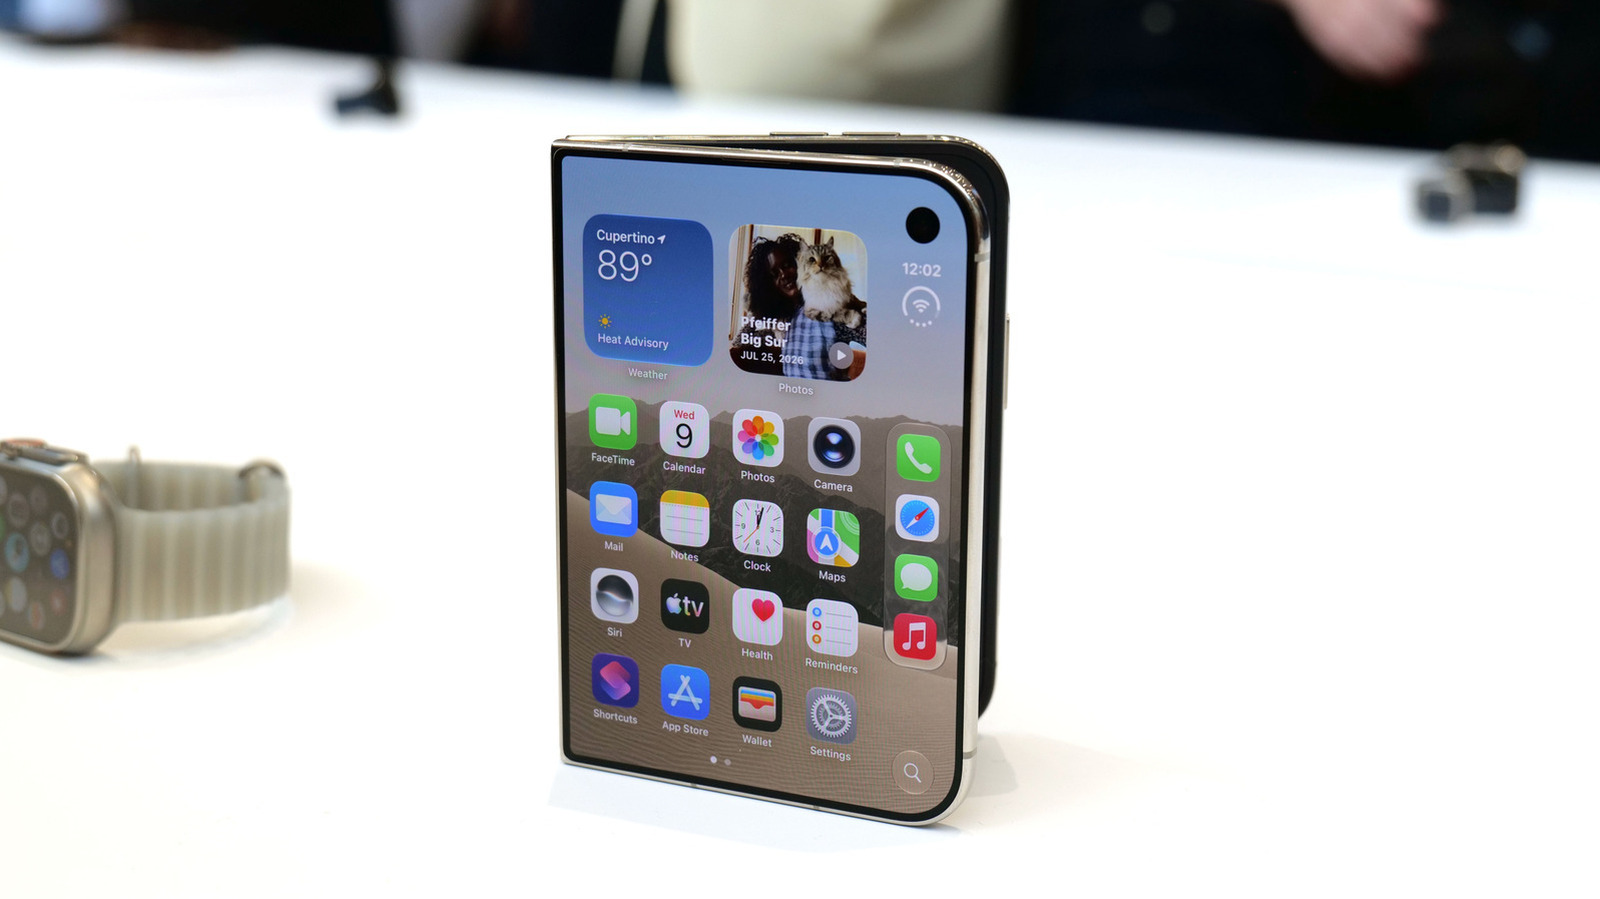
Apple's highly anticipated iPhone Duo, priced at $2,000, has gone on pre-order. While hailed as "Apple's most exciting device in a decade" for its innovative foldable design and immersive display, it comes with significant drawbacks like the absence of FaceID and a premium camera.
Tesla Unveils Thruster-Equipped Roadster, 2028 Production Targeted
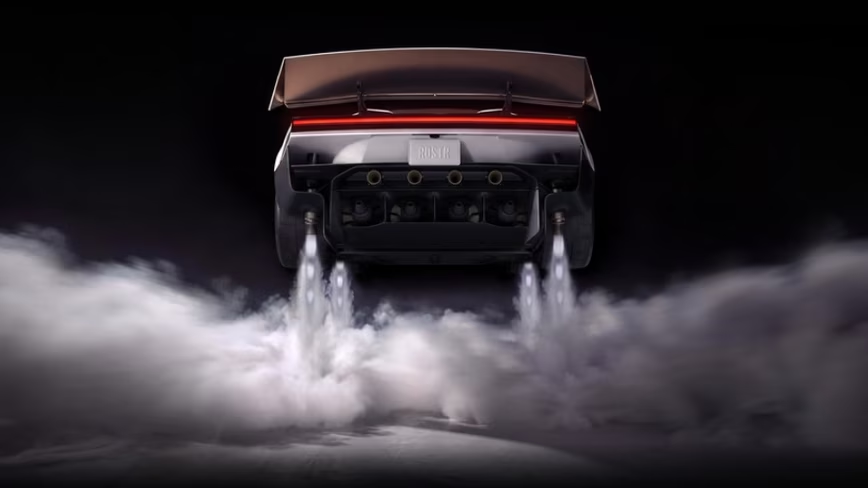
Tesla has unveiled its second-generation Roadster, featuring cold-gas thrusters co-developed with SpaceX, enabling it to jump and flip. The electric sports car demonstrated 0-60mph in an astonishing 0.81 seconds, with production targeted for 2028. This highly anticipated reveal also serves as a key recruitment tool for Tesla's ambitious AI and robotics initiatives.