
IndexCache Speeds Long-Context AI Models by 1.82x
IndexCache, a novel sparse attention optimizer by Tsinghua University and Z.ai, dramatically accelerates long-context AI models. It cuts up to 75% redundant computation, delivering up to 1.82x faster inference and significant cost savings.
Researchers from Tsinghua University and Z.ai have unveiled IndexCache, a novel sparse attention optimizer designed to dramatically accelerate long-context artificial intelligence models. This new technique slashes redundant computation by up to 75% in models utilizing the DeepSeek Sparse Attention (DSA) architecture, yielding impressive performance gains. Initial tests demonstrate up to 1.82x faster time-to-first-token and 1.48x quicker generation throughput, particularly for processing prompts up to 200,000 tokens long. This innovation promises to make demanding AI applications more responsive and cost-effective for enterprises.
Addressing the DSA Bottleneck
Large Language Models (LLMs) fundamentally rely on the self-attention mechanism, which calculates relationships between every token in a sequence. However, this process scales quadratically with context length, leading to significant computational and memory costs for extensive tasks like document analysis or multi-step agentic workflows. Sparse attention, as implemented in architectures like DeepSeek Sparse Attention (DSA), addresses this by having queries attend to only the most relevant subset of tokens, transforming core attention from quadratic to linear complexity.
Despite DSA's efficiency gains, a critical bottleneck remained. The "lightning indexer module" within DSA, responsible for selecting these relevant tokens, still operates with quadratic complexity at each layer. As context lengths expand, the computational load from these indexers skyrockets, particularly during the initial prompt processing, known as the "prefill" stage. This "indexer tax" substantially hindered the overall model speed.
IndexCache's Innovative Solution
The research team pinpointed a key inefficiency: the selected important tokens often remain consistent across consecutive transformer layers in DSA models, with empirical data showing 70% to 100% overlap. IndexCache capitalizes on this cross-layer redundancy by partitioning the model's layers into "full" (F) and "shared" (S) categories.
In this innovative design, only a few F layers actively calculate and cache fresh token indices. The majority, the S layers, bypass this intensive computation entirely, instead reusing the cached indices from the nearest preceding F layer. This approach directly targets the compute bottleneck of the indexers, differing from traditional KV cache compression techniques which focus on memory footprint. According to Yushi Bai, co-author of the paper, IndexCache is complementary to existing methods and can be combined with them.
Flexible Deployment and Training
IndexCache offers two primary deployment strategies. For developers working with pre-existing DSA models, a training-free method uses a "greedy layer selection" algorithm. This algorithm, calibrated with a small dataset, intelligently identifies optimal F and S layer placements, enabling up to 75% of indexers to be safely removed without compromising performance.
For teams building or extensively fine-tuning foundation models, a training-aware approach integrates a "multi-layer distillation loss" during training. This method trains indexers to select a consensus set of tokens relevant for multiple subsequent layers, inherently optimizing the network for cross-layer sharing. IndexCache is currently applicable to models built on the DSA architecture, including the latest DeepSeek and GLM families.
Real-World Performance Gains
Extensive evaluations on the 30-billion-parameter GLM-4.7 Flash model demonstrated significant real-world speedups. At a context length of 200,000 tokens, IndexCache, with 75% of indexers eliminated, reduced prefill latency from 19.5 seconds to 10.7 seconds, a 1.82x acceleration. During the decoding phase, per-request throughput jumped by 1.48x, from 58 to 86 tokens per second. Under full server load, total decode throughput saw an increase of up to 51%.
These efficiency gains directly translate into reduced operational costs for enterprises. Bai noted that long-context workloads such as Retrieval Augmented Generation (RAG), document analysis, and agentic pipelines could see approximately a 20% reduction in deployment costs and improved user-perceived latency. For shorter contexts, benefits average around 5%.
Crucially, these performance enhancements did not compromise reasoning capabilities. The training-free IndexCache-optimized 30B model maintained an average score of 49.9 on long-context benchmarks, nearly matching the original baseline's 50.2. It even surpassed the baseline on the complex AIME 2025 math reasoning benchmark, scoring 92.6 compared to 91.0. Preliminary tests on the massive 744-billion-parameter GLM-5 model also showed at least a 1.3x speedup on contexts over 100K while maintaining quality.
Future Outlook and Accessibility
Implementing the training-free IndexCache approach requires a calibration dataset that reflects real-world domain-specific workloads to optimize layer sharing patterns. Once calibrated, deployment is straightforward, with open-source patches already available on GitHub for popular inference engines like vLLM and SGLang.
Yushi Bai emphasizes that IndexCache's underlying philosophy signals a shift in AI model design. "Future foundation models will likely be architected with downstream inference constraints in mind from the beginning," he stated, suggesting a move towards designs inherently optimized for throughput and latency, rather than treating these as afterthoughts.
FAQ
Q: Which AI models can benefit from IndexCache?
A: IndexCache is specifically designed for models that utilize the DeepSeek Sparse Attention (DSA) architecture, including the latest DeepSeek models and the GLM family of models.
Q: How much faster can IndexCache make AI inference?
A: Depending on the context length and specific model, IndexCache can deliver significant speedups. For a 200,000-token context, it achieved up to 1.82x faster time-to-first-token and 1.48x faster generation throughput in tests, with preliminary results showing at least 1.3x speedup on very large models like GLM-5.
Q: Does IndexCache reduce the quality or accuracy of AI model outputs?
A: No, the research indicates that IndexCache maintains or even slightly improves reasoning capabilities. Tests showed the optimized models matched or outperformed baselines on various long-context benchmarks and math reasoning tasks.
Related articles

Apple Unveils iPhone Duo: Pricey Foldable Sees Soaring Demand
Apple has officially entered the foldable smartphone arena with the long-anticipated launch of the iPhone Duo. Priced starting at a hefty $1,999, the device features a 5.4-inch outer display and a larger 7.6-inch inner
Android 17 QPR2 Beta 7.1: The Performance Relief You've Been Waiting
Android 17 QPR2 Beta 7.1: Finally Fixing the QPR1 Performance Woes Verdict: Android 17 QPR2 Beta 7.1 is a crucial and highly anticipated software update for Google Pixel users, specifically targeting and resolving the

in-depth: Chicago-Area Cops Helped HSI Spy on Minnesota Anti-ICE
Chicago-area law enforcement, including local police and HSI agents, conducted undercover surveillance on Minnesota anti-ICE activists at an April 2, 2022, talk in Chicago. This operation was part of a federal conspiracy probe into 15 Minnesota activists facing felony charges related to immigration enforcement resistance. Civil liberties advocates have condemned the surveillance as a troubling intrusion into protected political activity.
TCG Pocket Responds: A Much-Needed Pace Shift for Pokémon Fans
Pokémon TCG Pocket is rolling out a major update for its second anniversary, primarily addressing player concerns about overwhelming content releases by shifting to a six-week set schedule. This aims to curb player decline and improve overall engagement by giving trainers more time to collect and strategize. The update also adds new collection methods, improved deck-building features, and enhanced trading functionality.

Mark Wahlberg on using AI in film ‘the right way’ and being open to
Actor Mark Wahlberg believes AI has a place in filmmaking if used responsibly for enhancement, not script generation or actor replacement. At TechCrunch Disrupt, he expressed openness to an AI likeness carrying on his legacy, managed by his family, and emphasized storytelling.
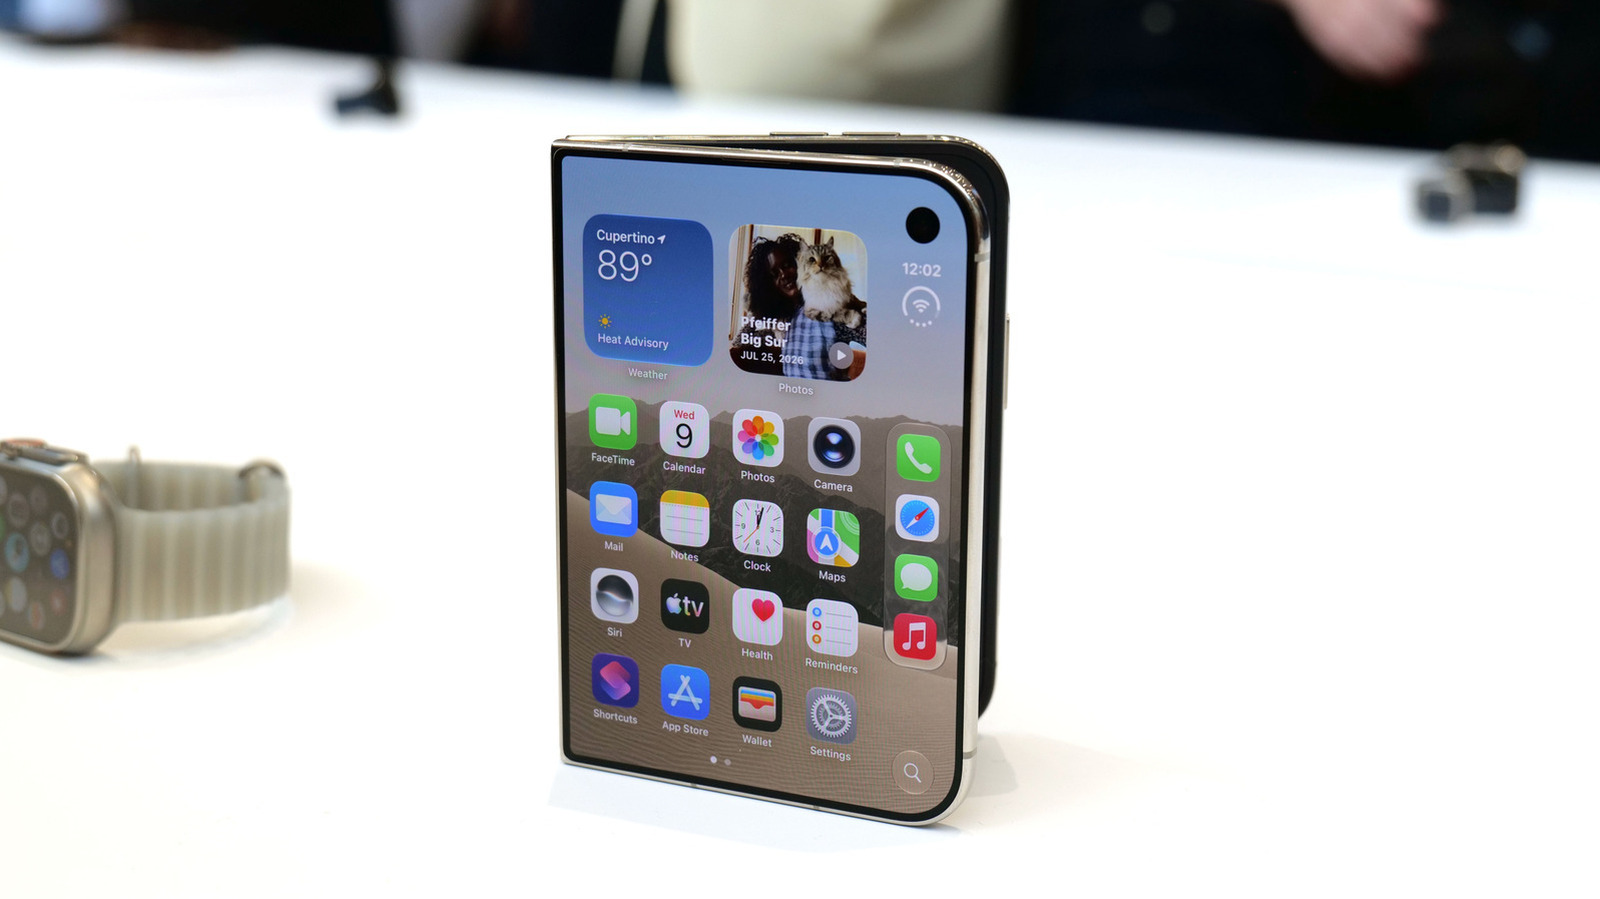
Apple iPhone Duo: A Daring Debut with Notable Compromises
Apple's highly anticipated iPhone Duo, priced at $2,000, has gone on pre-order. While hailed as "Apple's most exciting device in a decade" for its innovative foldable design and immersive display, it comes with significant drawbacks like the absence of FaceID and a premium camera.