
Build & Train a 25M Parameter LLM from Scratch on Your CPU
Explore how to build and train a 25-million parameter LLM directly on your CPU, stripping away the need for expensive GPU clusters. This hands-on approach reveals core LLM architecture, pre-training with cross-entropy loss, and post-training with Reinforcement Learning, allowing rapid iteration and direct observation of model behavior changes.
Large Language Models (LLMs) have captivated the tech world, pushing the boundaries of AI capabilities. However, the sheer scale of these models, often boasting billions of parameters, typically conjures images of vast GPU clusters and prohibitive cloud computing costs. This perception can deter individual developers from diving deep into their underlying mechanics.
But what if you could demystify modern frontier AI and gain hands-on experience with LLM architecture, pre-training, and fine-tuning – all on your everyday laptop or standard CPU? It's not just possible; it's an incredibly effective way to learn.
The Power of Scaling Down: Why a 25M Parameter LLM on CPU?
The core principles, mathematical foundations, and training workflows of even the largest LLMs remain fundamentally consistent, regardless of their scale. By constructing a 25-million parameter language model with a compact byte-level vocabulary, we achieve several critical advantages:
- Cost-Efficiency: Eliminate expensive cloud compute costs associated with massive GPU resources.
- Rapid Iteration: Training loops that might take hours or days on larger models can complete locally on your CPU in mere seconds. This speed is invaluable for experimentation.
- Direct Observation: The ability to rapidly iterate allows for immediate feedback. You can directly observe how subtle changes to data curricula, loss functions, and reward designs instantly alter the model's behavior, providing unparalleled insight into its learning process.
This scaled-down approach provides a practical sandbox for exploring complex AI concepts without the typical barriers to entry.
Unpacking Modern LLM Architecture
The project involves building a model that incorporates cutting-edge architectural elements, offering a practical understanding of how they function under the hood. Key components include:
- Hybrid Linear/Sparse Attention: This technique optimizes attention mechanisms, crucial for how LLMs process sequences, by combining both dense and sparse computations. This can lead to efficiency gains while retaining performance.
- Mixture of Experts (MoE): MoE layers allow a model to selectively activate different 'expert' sub-networks for different input tokens. This enables models to become much larger in terms of parameters without a proportional increase in computational cost during inference, as only a subset of experts is used for any given input.
- Tied Embedding Weights: By tying the input and output embedding weights, we reduce the total number of parameters, making the model more compact and potentially improving generalization.
- Multimodal Image Patch Inputs: This allows the language model to process visual information alongside text. By treating image patches as tokens, the model can develop an understanding that spans modalities, a critical step towards more general AI systems.
The Training Journey: From Random Characters to Code Proficiency
The model undergoes a two-phase training process, mirroring how many large-scale LLMs are developed:
Phase 1: Pre-Training from Zero with Cross-Entropy Loss
The initial phase is about foundational learning. The model begins by generating random characters. Through cross-entropy loss, a standard metric for classification tasks, it progressively learns to predict the next character or token in a sequence. This allows it to grasp fundamental patterns, syntax, and structure of languages – in this case, Python – step-by-step. This unsupervised learning phase builds the model's general understanding of language.
Phase 2: Post-Training with Reinforcement Learning (RL)
After pre-training, the model undergoes post-training using a lightweight Reinforcement Learning (RL) loop. This phase is critical for fine-tuning the model's behavior towards specific tasks and desired outcomes. Here's how it works:
- Task Execution: The model is prompted to write code.
- Automated Evaluation: This generated code is then run against automated unit tests.
- Reward Mechanism: Based on the success or failure of the unit tests, the model receives rewards. Successful code execution yields positive rewards, while failures lead to lower or negative rewards.
- Iterative Improvement: The RL loop uses these rewards to guide the model's learning, adjusting its internal parameters to produce better code in subsequent attempts. This iterative feedback mechanism enables the model to significantly boost its task success rate, moving from an initial 0% passing rate to successfully evaluating the majority of tasks.
Cultivating an AI Researcher's Mindset
Beyond the technical implementation, this hands-on experience also teaches you to approach problems like a modern AI researcher. This involves:
- Forming Testable Hypotheses: Developing clear, falsifiable statements about how changes might affect model behavior.
- Tweaking Parameters: Experimenting with hyper-parameters like 'temperature' (which influences the randomness of model outputs) and reward structures to observe their impact.
- Statistical Significance: Learning to check for real statistical significance across multiple seeds (different initial random states) to ensure that observed improvements are not merely due to chance.
This methodology fosters a scientific approach to model development and optimization.
Practical Takeaways
Building an LLM from scratch on your CPU, even a smaller one, is an unparalleled learning experience. It strips away the abstraction of massive cloud infrastructure and puts you directly in control of the model's entire lifecycle. You'll gain a deep, intuitive understanding of how these complex systems function, learn to experiment effectively, and develop a practical skillset applicable to larger-scale AI projects.
If you're eager to dive into the nitty-gritty of modern LLMs without needing an enterprise budget, this approach offers a direct path to profound insights.
FAQ
Q: What is the primary advantage of training a 25M parameter LLM on a CPU instead of a GPU cluster?
A: The primary advantage is the elimination of high cloud compute costs associated with GPU clusters. Additionally, it enables rapid iteration, allowing training loops to complete in seconds on a CPU, which provides immediate feedback for observing the impact of changes to the model's data, loss functions, and reward designs.
Q: How does a Mixture of Experts (MoE) architecture contribute to LLM efficiency?
A: MoE layers improve efficiency by allowing the model to have a very large number of parameters (many 'experts') without requiring all parameters to be activated for every input. Instead, a routing mechanism selects only a subset of experts to process specific input tokens, significantly reducing the computational cost during inference compared to a dense model of similar parameter count.
Q: What is the role of Reinforcement Learning (RL) in the post-training phase of this LLM?
A: In the post-training phase, RL is used to fine-tune the pre-trained LLM for specific tasks, such as generating functional code. The model writes code, which is then evaluated by automated unit tests. Based on the success or failure of these tests, the model receives rewards, which it uses to iteratively learn and improve its code generation capabilities, leading to a higher task success rate.
Related articles
TCG Pocket Responds: A Much-Needed Pace Shift for Pokémon Fans
Pokémon TCG Pocket is rolling out a major update for its second anniversary, primarily addressing player concerns about overwhelming content releases by shifting to a six-week set schedule. This aims to curb player decline and improve overall engagement by giving trainers more time to collect and strategize. The update also adds new collection methods, improved deck-building features, and enhanced trading functionality.
Ditch Merge & Center: The Better Way to Align Text in Excel
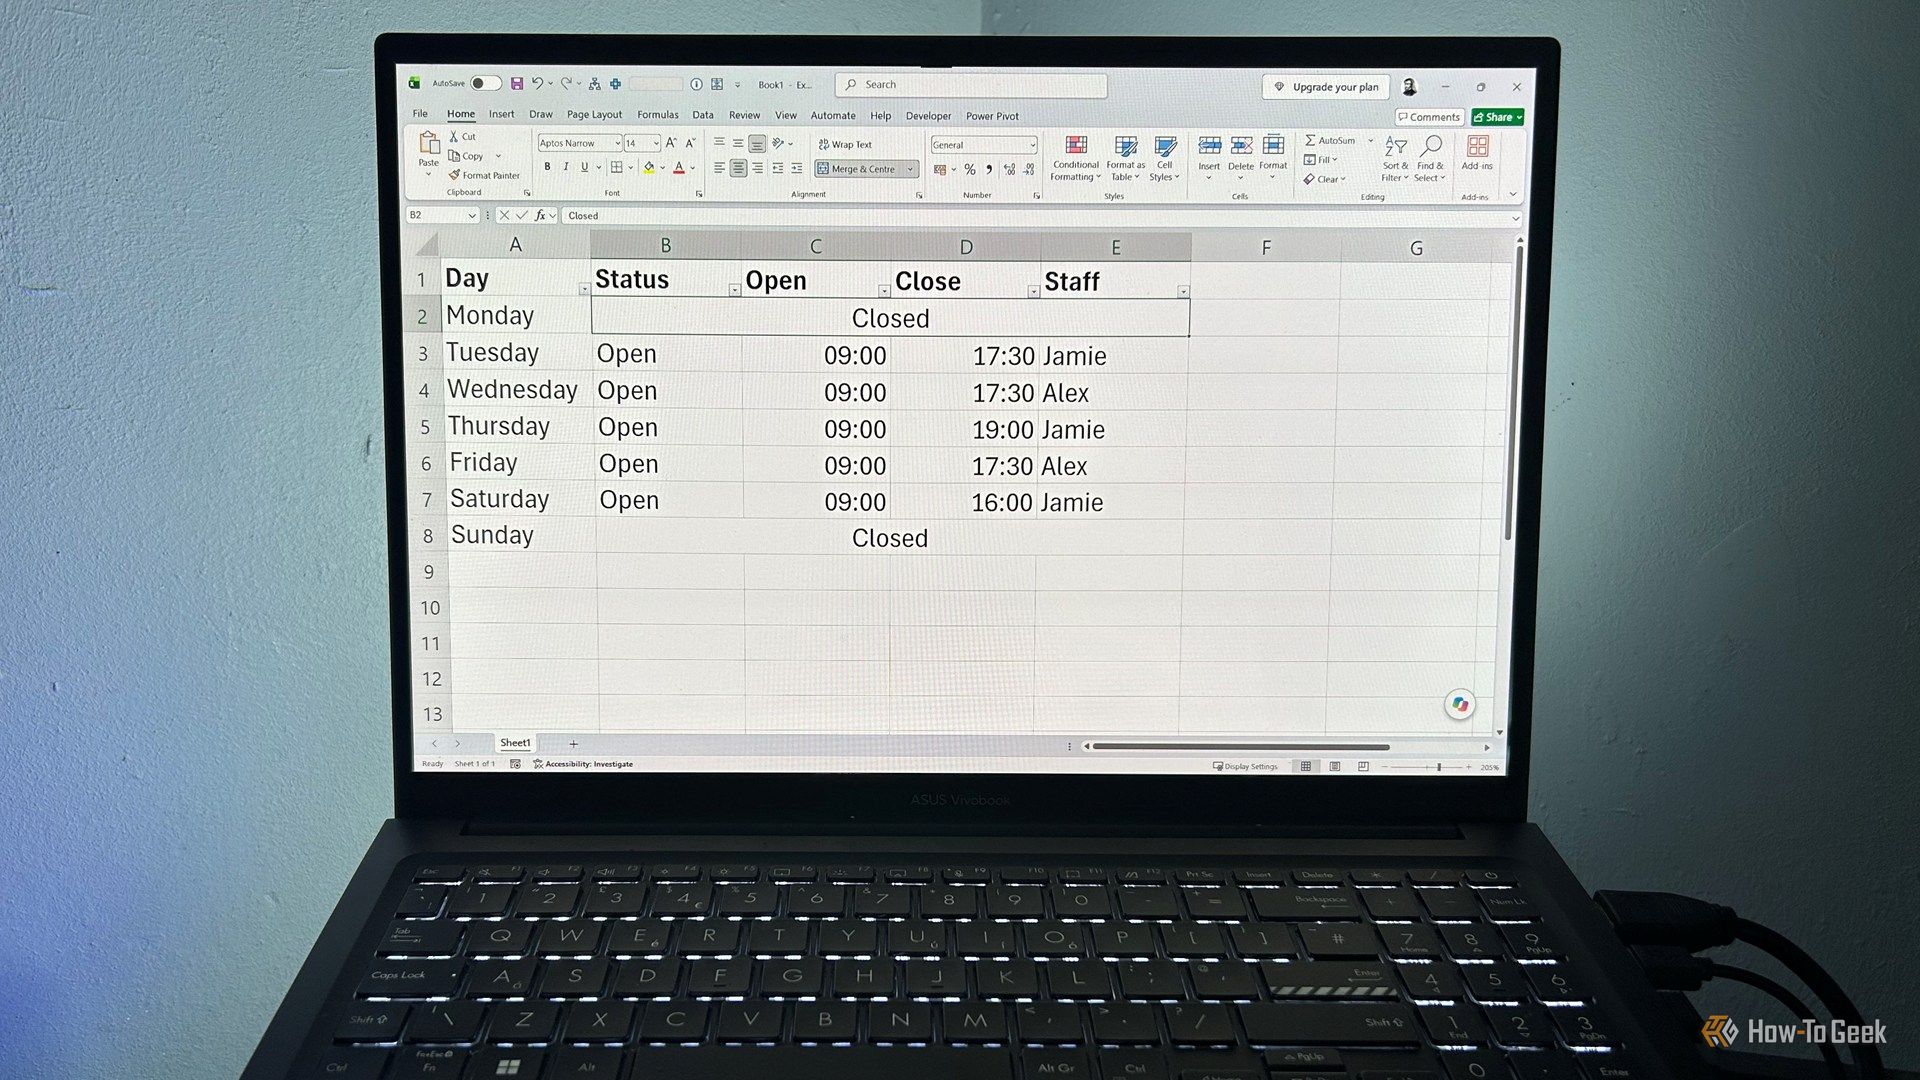
Learn to use Excel's "Center Across Selection" to align text across cells without merging, avoiding common data manipulation issues. This guide provides steps to utilize this newly accessible feature and add it to your Quick Access Toolbar.
Ars Technica's Rocket Report: Your Essential Space Industry Briefing
Quick Verdict Ars Technica's Rocket Report, presented by veteran space reporter Stephen Clark, offers an invaluable and meticulously organized weekly (or similar frequency, implied by "Edition 9.15") digest of the most

AI's Confidence vs. Formal Methods' Rigor: Design Flaws & Verification
While AI accelerates code generation, formal methods remain critical for ensuring system correctness. Languages like TLA+ and tools like Quint enable developers to model and verify system designs before coding, catching subtle flaws. Quint makes formal methods more accessible with developer-friendly syntax and executability. This approach is vital for verifying AI-generated code through trace validation and model-based testing, ensuring reliability against real-world data.
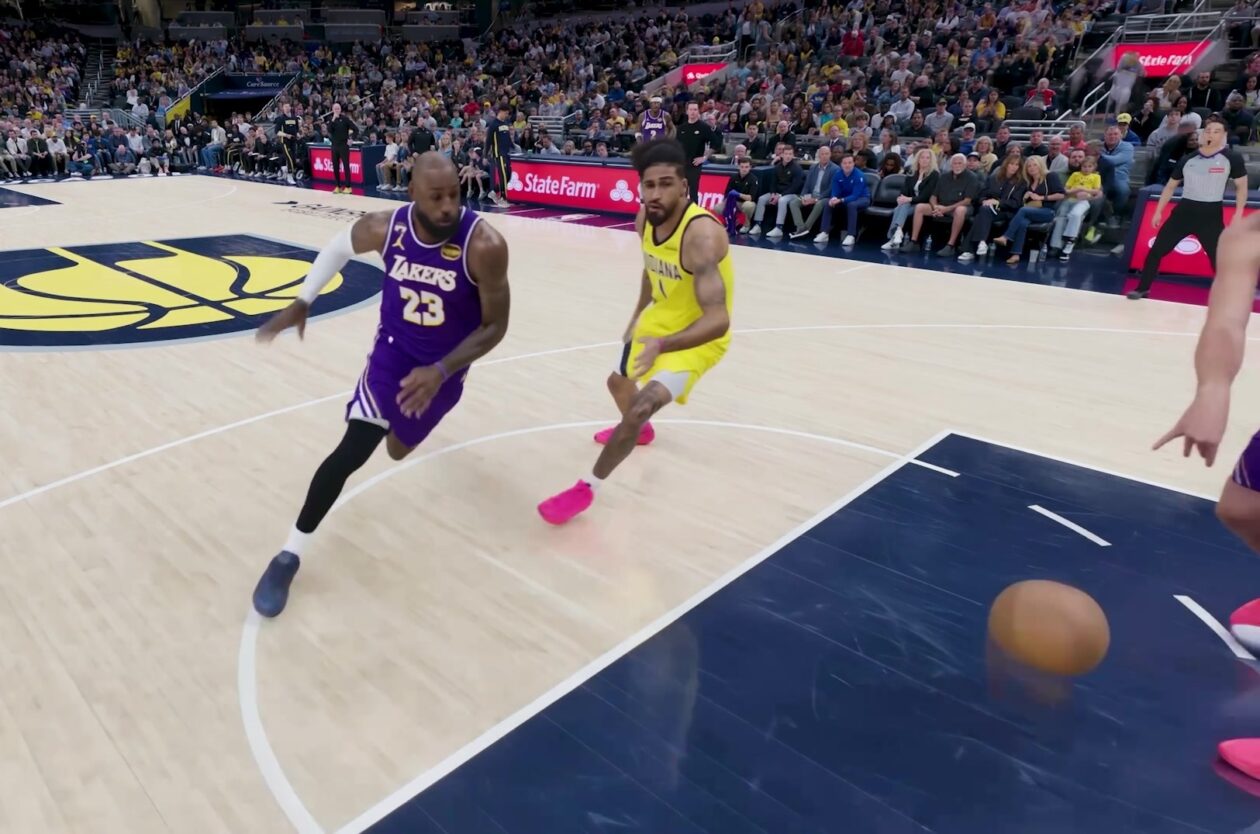
Amazon Prime Video Launches AI-Powered Prime 360 for NBA Coverage
Amazon Prime Video is elevating its NBA coverage with the introduction of Prime 360, an AI-powered replay system offering immersive, 'fly through' views of the action. Kicking off its second season, Prime Video also adds Yahoo fantasy integration and gains exclusive Eastern Conference Finals rights, expanding its tech-driven sports broadcast. The new features aim to deliver a unique and interactive viewing experience for basketball fans.
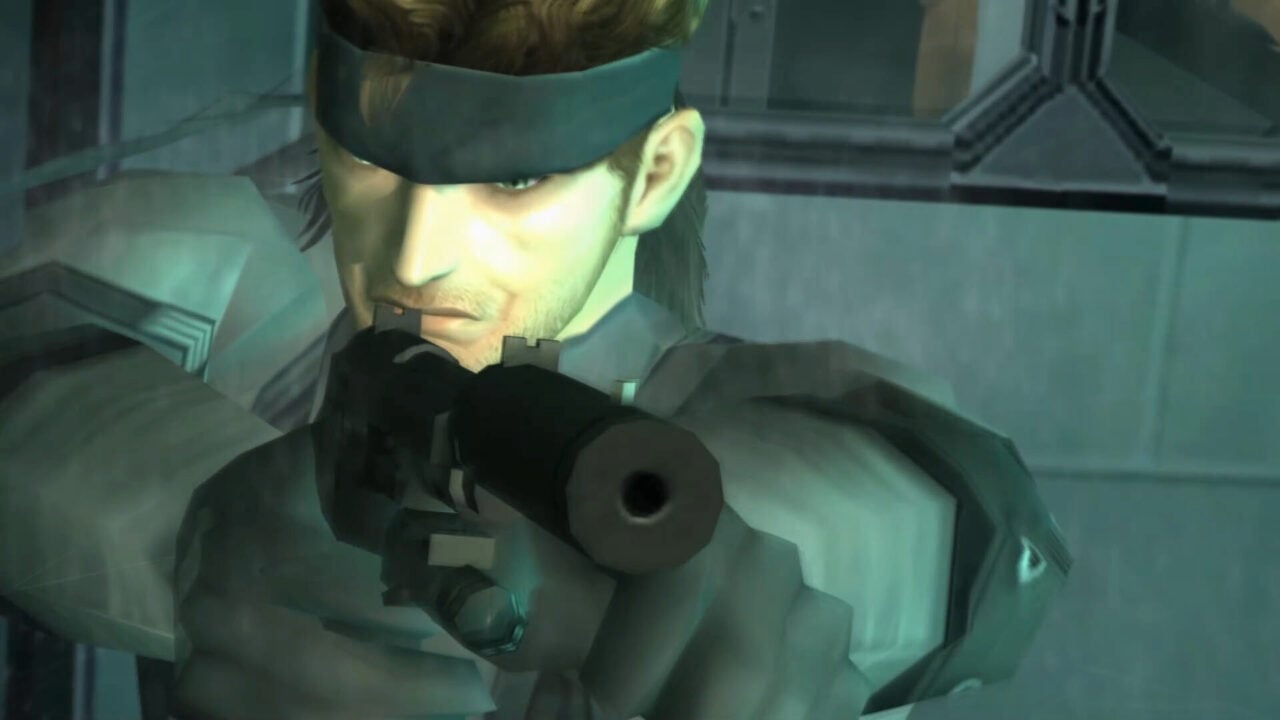
Kojima Compares Divisive New Film 'Digger' to MGS2's Prescient Vision
Gaming icon Hideo Kojima has praised the divisive 2026 film *Digger*, drawing intriguing parallels to his own prophetic game, *Metal Gear Solid 2*. Both works, he explains, uniquely explore the dangers of misinformation and a fragmented digital reality, anxieties he shares with *Digger*'s director, Alejandro González Iñárritu.