
AI Paper Review: Gradients for Generative Modeling
This paper introduced score-based generative modeling, a paradigm shift to estimating local gradients of the data distribution. Leveraging Noise Conditional Score Networks and annealed Langevin dynamics, it offered a stable, tractable alternative to GANs and likelihood models, laying the foundation for modern diffusion models.

Modern generative AI, especially diffusion models, has made incredible strides in image synthesis, video generation, and more. These models start with random noise and gradually transform it into realistic data. But how do they know which tiny adjustment pushes an image closer to reality versus further away? What guides them through this transformation?
In 2019, Yang Song and Stefano Ermon's paper, "Generative Modeling by Estimating Gradients of the Data Distribution," provided an elegant, mathematically principled answer. Their work introduced score-based generative modeling, shifting the focus from directly learning the entire data distribution to estimating its score—the local direction pointing toward more realistic data. This seemingly modest conceptual shift became a cornerstone for modern diffusion models.
The Problem with Prior Generative Approaches
Before score-based models, two main paradigms dominated generative AI: likelihood-based models and Generative Adversarial Networks (GANs). Both achieved success but came with significant trade-offs.
- Likelihood-based models often required restrictive architectural assumptions or relied on computationally expensive approximations. While providing a clear training objective, they often struggled with flexibility and scalability to complex data.
- Generative Adversarial Networks (GANs), on the other hand, excelled at producing high-quality samples. However, their adversarial training process was notoriously unstable, often difficult to optimize, and lacked a clear, tractable learning objective for quantitative evaluation.
This landscape presented a critical gap: a unified framework that could combine high-quality generation, stable optimization, architectural flexibility, and a tractable objective remained elusive. This is precisely the gap that score-based generative modeling aimed to bridge.
Score-Based Generative Modeling: The Core Idea
The central insight of Song and Ermon's work is elegantly simple: instead of estimating the probability of every point in a high-dimensional space, it's sufficient to learn the score function. The score is defined as the gradient of the log-density of the data distribution. Think of it like this: rather than mapping every peak and valley of a mountain range (the data distribution), you only need to learn which direction points uphill from any given location. This local 'uphill' direction is the score, guiding samples toward regions of higher data probability.
This framework naturally divides into two stages:
- Learning the Score Field (Training): A neural network is trained to approximate this score function directly from data using a technique called score matching. This avoids the intractable problem of explicitly calculating data densities.
- Sampling with Langevin Dynamics (Inference): Once the score field is learned, new samples are generated. This process starts from random noise and iteratively follows the learned score directions. A small amount of Gaussian noise is injected at each step to encourage exploration and prevent getting stuck in local minima. Over many steps, this gradually transforms random noise into data that resembles the training distribution.
Challenges of Naive Score-Based Modeling
While theoretically appealing, applying this naive approach directly to real-world data like images revealed two critical challenges:
- The Manifold Hypothesis: Real-world data is often believed to reside on low-dimensional manifolds embedded within a much higher-dimensional space. Outside this manifold, the probability density is effectively zero, making the score ill-defined. This violates assumptions of classical score matching and leads to unstable training.
- Low-Density Regions: Accurately estimating the score is particularly difficult in sparsely populated regions where training data is scarce. Ironically, these are precisely the regions where the sampling process typically begins (i.e., pure noise).
Experiments confirmed these issues: a score matching model trained directly on images like CIFAR-10 failed to converge. However, perturbing the data with even a tiny amount of Gaussian noise stabilized training, demonstrating that spreading the data beyond its strict manifold was crucial.
The Solution: Noise Conditional Score Networks (NCSNs) and Annealed Langevin Dynamics
To address these limitations, the authors introduced a two-pronged solution:
-
Noise Conditional Score Networks (NCSNs): The core idea here is to perturb the training data with multiple levels of Gaussian noise. This strategy spreads the data points beyond their low-dimensional manifold into the surrounding ambient space, enriching the training distribution. A single neural network, the NCSN, learns the score for all these resulting noisy distributions, conditioned on the specific noise level applied. This provides a robust, well-defined score estimate across the entire ambient space, even in regions previously devoid of data.
-
Learning NCSNs via Denoising Score Matching: To train the NCSN efficiently, the paper leveraged Denoising Score Matching (DSM). Unlike the original score matching objective which required computing the expensive trace of the Jacobian (a computational bottleneck for deep networks and high-dimensional data), DSM perturbs each training sample with Gaussian noise and trains the network to predict the score of this noisy distribution. This reformulation significantly simplifies optimization, making it scalable and practical for real-world applications. Sliced Score Matching (SSM) was also discussed as an alternative, but DSM proved more computationally efficient.
-
NCSN Inference via Annealed Langevin Dynamics: For sampling, the model employs a technique called annealed Langevin dynamics. The process begins with heavily perturbed samples (pure noise). Iteratively, the noise level is progressively reduced in stages. At each stage, the NCSN's corresponding score estimate guides the samples toward increasingly realistic regions of the data distribution. This 'annealing' process smoothly transitions from noisy, abstract representations to high-quality, realistic data.
Impact and Legacy
This framework's strengths are manifold: it avoids the instability of adversarial training, doesn't require sampling during optimization, offers architectural flexibility for the score network, and provides a tractable training objective for quantitative evaluation. Experiments on datasets like MNIST, CelebA, and CIFAR-10 demonstrated that the proposed method produced samples competitive with contemporary GANs and likelihood-based models, achieving a state-of-the-art Inception Score on CIFAR-10 at the time of publication.
Beyond just image generation, the learned score representations also enabled effective image inpainting, highlighting the model's ability to capture rich structural information about the underlying data. Crucially, the ideas introduced in this paper became the conceptual foundation for the score-based diffusion models that have rapidly reshaped generative AI in subsequent years.
Practical Takeaways
For developers, this paper offers a profound shift in thinking about generative models. It demonstrated that we don't necessarily need to perfectly model an entire complex probability distribution to generate high-quality data. Instead, by learning the local 'direction of realism' (the score) and cleverly navigating through noise space, we can achieve impressive results. The principles of perturbing data to make scores well-defined and using an annealed sampling process are now fundamental to many state-of-the-art generative models, making this paper essential reading for anyone working with diffusion models.
FAQ
Q: What is the "score" in score-based generative modeling, and why is it preferred over directly modeling the data distribution?
A: The score is the gradient of the log-density of the data distribution, indicating the local direction toward regions of higher probability. It's preferred because directly modeling the entire data distribution is often mathematically intractable or computationally restrictive, whereas learning the local gradient can be done more efficiently and stably.
Q: How do Noise Conditional Score Networks (NCSNs) address the "manifold hypothesis" problem?
A: The manifold hypothesis posits real-world data lies on low-dimensional manifolds, making the score ill-defined outside. NCSNs address this by perturbing data with multiple levels of Gaussian noise, spreading the data beyond the manifold into the ambient space. This enriches the training distribution, providing well-defined score estimates even in previously sparse regions.
Q: What is the role of Denoising Score Matching (DSM) in training NCSNs?
A: DSM is the practical method used to train NCSNs. It perturbs each training sample with Gaussian noise and trains the network to predict the score of this noisy distribution. This approach is computationally efficient, as it removes the need to compute the expensive Jacobian trace required by the original score matching objective, making it scalable for deep neural networks and high-dimensional data.
Related articles
Android 17 QPR2 Beta 7.1: The Performance Relief You've Been Waiting
Android 17 QPR2 Beta 7.1: Finally Fixing the QPR1 Performance Woes Verdict: Android 17 QPR2 Beta 7.1 is a crucial and highly anticipated software update for Google Pixel users, specifically targeting and resolving the

DJI Solo Video Setups: Smart Choices for Lone Creators
This review delves into DJI's recommended solo video setups, highlighting the Osmo Pocket 3 Creator Combo as a top pick for its integrated camera, gimbal, and mic. It also covers stabilizers like the Osmo Mobile 8 and RS 4, and the DJI Mic Mini series for enhanced audio, providing honest pros, cons, and clear buying advice.
TCG Pocket Responds: A Much-Needed Pace Shift for Pokémon Fans
Pokémon TCG Pocket is rolling out a major update for its second anniversary, primarily addressing player concerns about overwhelming content releases by shifting to a six-week set schedule. This aims to curb player decline and improve overall engagement by giving trainers more time to collect and strategize. The update also adds new collection methods, improved deck-building features, and enhanced trading functionality.

Mark Wahlberg on using AI in film ‘the right way’ and being open to
Actor Mark Wahlberg believes AI has a place in filmmaking if used responsibly for enhancement, not script generation or actor replacement. At TechCrunch Disrupt, he expressed openness to an AI likeness carrying on his legacy, managed by his family, and emphasized storytelling.
Apple iPhone Duo: A Daring Debut with Notable Compromises
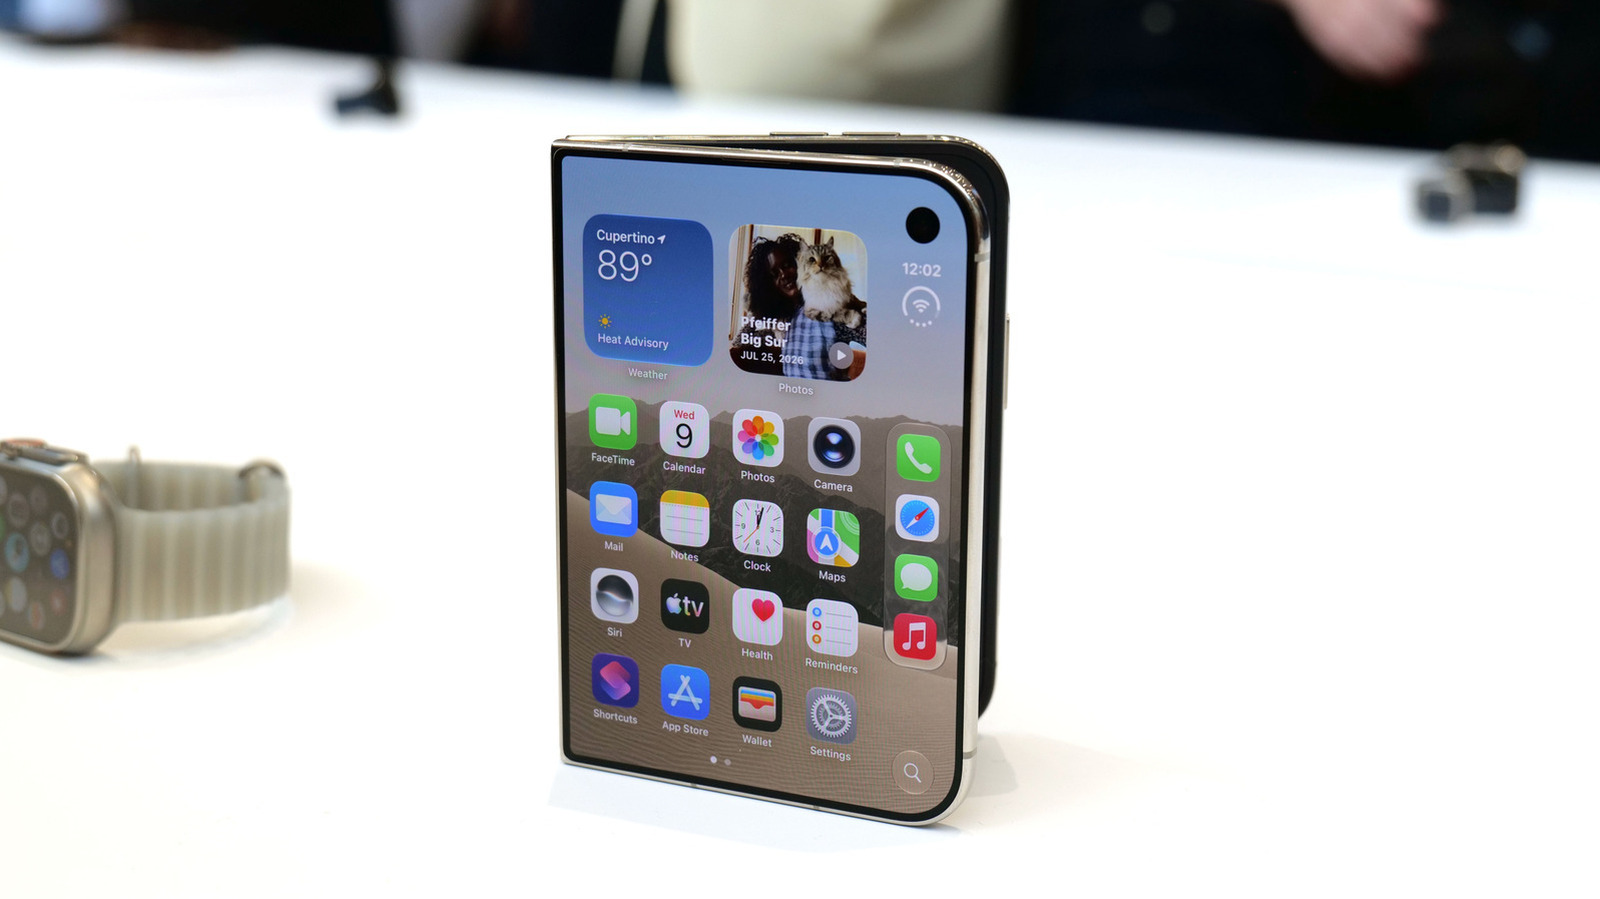
Apple's highly anticipated iPhone Duo, priced at $2,000, has gone on pre-order. While hailed as "Apple's most exciting device in a decade" for its innovative foldable design and immersive display, it comes with significant drawbacks like the absence of FaceID and a premium camera.
Tesla Unveils Thruster-Equipped Roadster, 2028 Production Targeted
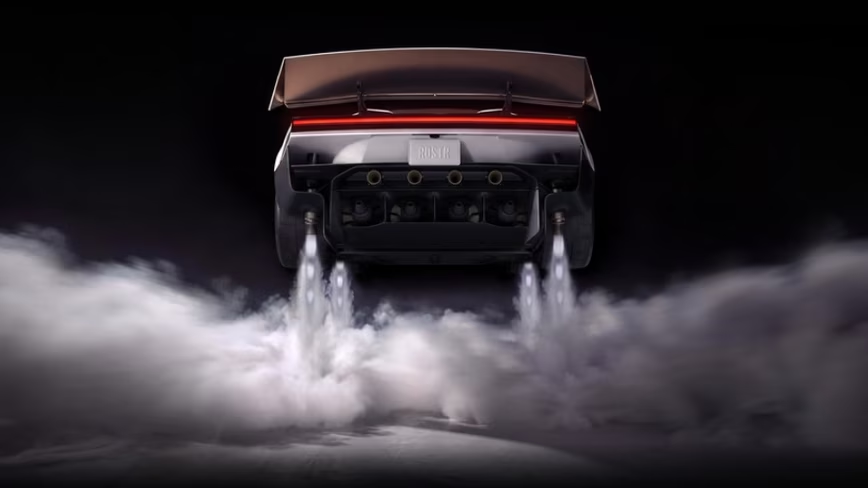
Tesla has unveiled its second-generation Roadster, featuring cold-gas thrusters co-developed with SpaceX, enabling it to jump and flip. The electric sports car demonstrated 0-60mph in an astonishing 0.81 seconds, with production targeted for 2028. This highly anticipated reveal also serves as a key recruitment tool for Tesla's ambitious AI and robotics initiatives.